
 Login

Normal view
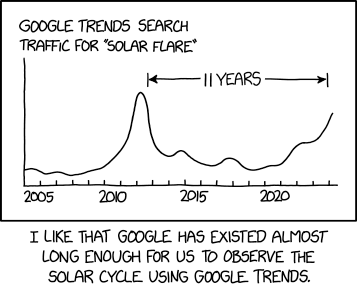
Google Solar Cycle
7 May 2024 at 19:00
Hígado: un gran órgano, una gran responsabilidad
8 May 2024 at 18:32
Los problemas que puede enfrentar el hígado son varios y las causas igual de diversas. Conversando con el Dr. Pablo Moreno Franco, durante el congreso de la Asociación Panameña de Medicina Crítica y Terapia Intensiva, pudimos conocer sus puntos de vista con respecto a este, el órgano interno más grande del cuerpo humano.
Para el especialista que trabaja para Mayo Clinic, si bien, la hepatitis y otras enfermedades virales, son las más relacionadas por las personas con el hígado, bajo su experiencia este es un mal que ataca más a países asiáticos, mientras que en occidente se lo atribuye al consumo indiscriminado de medicamentos.
“En occidente, las causas más comunes de fallos hepáticos son actualmente la intoxicación por acetaminofén. Las personas toman medicamentos con acetaminofén muy, muy a menudo. También tenemos individuos que están teniendo problemas, digamos psicológicos, y deciden hacer intentos suicidas, y lo primero en que encuentran en casa es acetaminofén. Y he tratado muchachos que en realidad no querían suicidarse, solo querían hacer el gesto de intento suicida, y creen que el acetaminofén no iba a causarles ningún daño real”, cuenta Moreno Franco, quien recalca que tomar cantidades altas de medicamentos acetaminofén pueden causar fallas hepáticas, aunque con esto no quiere decir que no se deba tomar el medicamento, sino con moderación o como ordene el médico.
Otra práctica relacionada con los fallos hepáticos es el consumo de alcohol. Aquí el intensivista, especializado en la unidad de cuidados críticos, cree que es un tema que debe analizarse desde varios ángulos. Primero, hace una diferencia de género. “Por ejemplo, simplemente digamos por la cantidad de alcohol que puede metabolizar un hígado de una mujer versus el hígado de un hombre y es simplemente la fisiología y el tamaño. Y con eso se recomienda que para los varones entre 2 y 3 tragos por semana y para las mujeres limitarse a 2 o menos tragos por semana. Entonces, eso es, en términos generales, para prevenir la cirrosis a largo plazo”.
Cabe aclarar que se trata de bebidas alcohólicas que tengan entre 30% a 40% de alcohol.
“En el caso específico de la cerveza generalmente tiene mucho menos que eso, tiene un 10-12%. Así que, eso varía mucho dependiendo de la ingesta. Desde el punto de vista, digamos, social, yo pienso que si alguien va a salir una vez a la semana y tomarse unas cervezas no es ningún problema, siempre y cuando se haga con moderación. El problema es que muchas veces los individuos se acostumbran y primero fueron dos y después tres y después cinco, porque existe una tolerancia y ya se convierte en una dependencia”, recomienda Moreno Franco, explicando que si bien la cirrosis demora muchos años en desarrollarse (entre 10 y 15 años), ha tenido pacientes jóvenes que comenzaron a tomar desde adolescentes y tienen unos 20 y tanto de años, y ya padecen cirrosis.
En el caso de Panamá, las bebidas alcohólicas no están solamente asociadas a fiestas ocasionales, sino a la más popular de todas las celebraciones del istmo: el carnaval.
“Yo como buen panameño, no les digo a los panameños que no carnavaleen. Un consumo esporádico, digamos, si una persona solamente toma en carnavales, eso como tal no afecta la función hepática de forma significativa. Se puede carnavalear, salir y esparcirse. Pero lo que es importante es saber que un consumo excesivo de alcohol, sobre todo en un periodo de días, puede generar una hepatitis alcohólica.
La moderación en consumo de medicamentos y alcohol parece ser la clave para mantener un hígado sano, pero, hay otros aspectos importantes que las personas no asocian con fallas hepáticas que pueden causar iguales estragos.
“Hemos visto individuos que consumen sobre todo bebidas o medicamentos que ofrecen perder peso de forma aguda. O algunos tés. Pueden ir a una persona que trabaje con hierba y esas cosas y les dan unos tés que el individuo no sabe lo que son. Hemos tenido casos de falla hepática aguda, por ingesta de este tipo de té. Una vez tuve una paciente de unos 28 años con falla hepática aguda por tomar tés que no sabía qué contenía”, recuerda el especialista, aclarando que los tés que venden en el mercado, con sus ingredientes específicos y demás, son aptos para el consumo.
Pero, los francos de cuidado del hígado son varios, y otro a tener en cuenta es la obesidad. El especialista dice que en occidente el principal problema actual que está llevando al trasplante es el sobrepeso crónico. “Son pacientes que viven toda una vida con sobrepeso y en Panamá eso se ha puesto mucho más prevalente. La combinación de nuestras comidas autóctonas con lo importado y sobre todo las bebidas azucaradas. Eso lleva a los pacientes a que desarrollen una inflamación crónica del hígado que termina convirtiéndose en una cirrosis”.
Moreno Franco recomienda cuidar el peso, mantener actividad física. También recuerda que la obesidad no se limita a obesidad mórbida, sino que hay que mirar el índice de masa corporal y de esa forma calcularla a base de su estatura y peso.
Trasplantes
Si bien existen las cirugías de trasplante de hígado, esta es una de las cirugías abdominales más grandes que se realizan. Lo que se traduce en un alto costo para el paciente, sin contar que la cantidad de donantes no es muy alta. Por lo que el Dr. Pablo Moreno Franco hace un llamado a los panameños a ser donantes de órganos y así salvar otras vidas.
Esperanza
El especialista se muestra positivo al decir que la medicina ha avanzado de forma que muchas de las causas comunes de mortalidad por falla hepática han disminuido. Medicamentos para tratar la hepatitis C, cirugías bariátricas para los pacientes que no han podido bajar de peso por las formas usuales (dieta, ejercicio, etc.), y cada vez en Panamá se realizan más trasplantes de hígado. Yéndose más futurista, también comenta sobre los futuros trasplantes de hígado de puerco, lo que puede aumentar la disponibilidad de órganos.

Spaces Bucket Creates
7 May 2024 at 15:03
May 7, 20:03 UTC
Resolved - Our Engineering team has confirmed that the issue with Spaces Buckets creates in multiple regions has been fully resolved.
If you continue to experience any problems, please open a support ticket from within your account. Thank you for your patience and we apologize for the inconvenience.
May 7, 19:06 UTC
Monitoring - Our Engineering team has implemented a fix to resolve the issue affecting creation of Spaces Buckets in multiple regions and is monitoring the situation closely.
The impact has subsided and users should no longer experience issues creating Spaces Bucket both through the cloud control panel and via API.
We will post an update as soon as the issue is fully resolved.
May 7, 14:07 UTC
Investigating - Our Engineering team is investigating an uptick in error rates for users creating Spaces Buckets in multiple regions, starting May 3.
We have rolled back a recent change in our systems in an effort to address the issue. However, we are still investigating and users may still experience errors when attempting to create Spaces Buckets, both through the cloud control panel and via API.
We apologize for the inconvenience and will share an update once we have more information.
NYC2 Network Maintenance 2024-05-14
14 May 2024 at 20:38
May 15, 01:38 UTC
Completed - During the maintenance, our Engineering team observed possible connectivity issues between Droplets and networking services like LBaaS.
Due to such unforeseen issues, our Engineering team has decided to rollback this maintenance for now and will be rescheduling it at a later date.
We apologize for the inconvenience and the unexpected downtime to services. If you have any questions or continue to experience issues, please reach out via a Support ticket on your account.
May 14, 22:00 UTC
In progress - Scheduled maintenance is currently in progress. We will provide updates as necessary.
May 7, 04:13 UTC
Scheduled - Start: 2024-05-14 22:00 UTC
End: 2024-05-15 02:00 UTC
During the above window, our Networking team will be making changes to core networking infrastructure, to improve performance and scalability in the NYC2 region.
Expected impact:
These upgrades are designed and tested to be seamless and we do not expect any impact to customer traffic due to this maintenance. If an unexpected issue arises, affected Droplets and Droplet-based services may experience increased latency or a brief disruption in network traffic. We will endeavor to keep any such impact to a minimum.
If you have any questions related to this issue please send us a ticket from your cloud support page. https://cloudsupport.digitalocean.com/s/createticket
Create Failures in NYC3
6 May 2024 at 23:41
May 7, 04:41 UTC
Resolved - Our Engineering team has confirmed the complete resolution of the issue at 03:51 UTC.
Creating Droplets, all Droplet-based services including Kubernetes Clusters, Managed Databases, Load Balancers, and Snapshots are now working as expected in the NYC3 region.
Thank you for being so patient. If you continue to experience any problems, please open a support ticket from within your account.
May 7, 04:11 UTC
Monitoring - Our Engineering team has investigated and identified an issue with creating resources in the NYC3 region. Between approximately 03:18 UTC - 03:51 UTC, customers may have experienced errors when creating Droplets and Droplet-based services including Managed Kubernetes, Managed Databases, Load Balancers, and snapshots.
Our team has implemented a fix to restore the ability to create resources and is monitoring the region. We will post an update as soon as the issue is fully resolved.
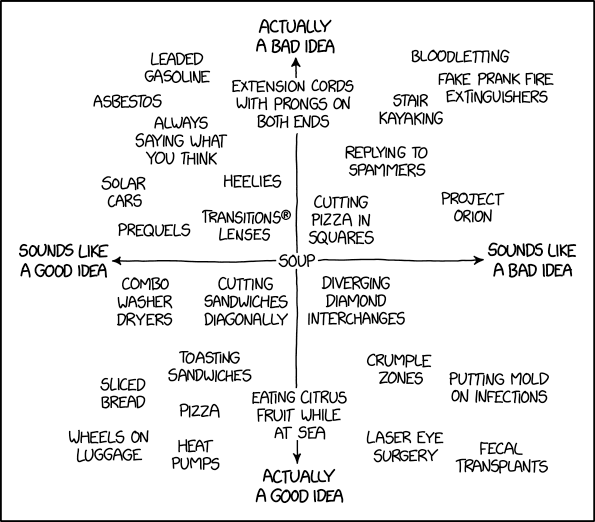
Good and Bad Ideas
5 May 2024 at 19:00
Rescheduled: NYC2 Network Maintenance 2024-05-09
9 May 2024 at 09:31
May 9, 14:31 UTC
Completed - The scheduled maintenance has been completed.
May 9, 12:00 UTC
In progress - Scheduled maintenance is currently in progress. We will provide updates as necessary.
May 3, 19:17 UTC
Scheduled - Start: 2024-05-09 12:00 UTC
End: 2024-05-09 15:00 UTC
During the above window, our Networking team will be making changes to core networking infrastructure, to improve performance and scalability in the NYC2 region. This is a rescheduled maintenance event previously attempted on 2024-05-02.
Expected Impact:
These upgrades are designed and tested to be seamless and we do not expect any impact on customer traffic due to this maintenance.
If an unexpected issue arises, affected Droplets and Droplet-based services could experience increased latency or disruption in public network traffic for a short period of time. If an unexpected issue does occur, our team is prepared to rollback to a safe state to quickly restore public networking. We expect that traffic would be impacted for a period of 5-10 minutes at most in that case.
If you have any questions related to this issue please send us a ticket from your cloud support page. https://cloudsupport.digitalocean.com/s/createticket
App Platform and Container Registry
6 May 2024 at 13:43
May 6, 18:43 UTC
Resolved - Our Engineering team has confirmed that the issue with our App Platform and Container Registry services has been fully resolved. If you continue to experience any trouble with these services, please open a ticket with our support team. Thank you for your patience and we apologize for the inconvenience.
May 6, 18:00 UTC
Monitoring - Our engineering team has implemented a fix to resolve the issue with our App Platform and Container Registry services and is monitoring the situation closely. We will post an update as soon as the issue is fully resolved.
May 6, 15:30 UTC
Update - Our Engineering team is still investigating the issue with App Platform and Container Registry. Currently, only a subset of users will continue to see errors with App Platform deployments and Container Registry.
We will post an update as soon as additional information is available.
May 6, 10:29 UTC
Investigating - Our Engineering team is investigating an issue with the DigitalOcean Container Registry and App Platform. At this time, users may find App Platform builds failing. Users may also experience issues while pushing images to the DigitalOcean Container Registry.
We apologize for the inconvenience and will share an update once we have more information.
DNS Resolution in Multiple Regions
5 May 2024 at 11:50
May 5, 16:50 UTC
Resolved - Our Engineering team has resolved the issue impacting DNS resolution across multiple regions. The functionality is restored completely and the DNS queries should now be resolving normally.
If you continue to experience problems, please open a ticket with our support team. We apologize for any inconvenience.
May 5, 15:31 UTC
Monitoring - Our Engineering team has implemented a fix to resolve the issues with the DNS resolution and is monitoring the situation. DNS queries are now succeeding without any failures as the functionality has started to recover.
We will continue to monitor this at our end and will share an update once the problem is resolved completely.
May 5, 14:08 UTC
Identified - Our engineering team continues to work on a fix for the issue impacting DNS resolution across multiple regions. At this time, users will continue to experience intermittent issues with DNS resolution impacting droplet based services.
We apologize for the inconvenience, and will post an update as soon as additional information is available.
May 5, 12:55 UTC
Investigating - Our Engineering team is investigating an issue with intermittent failures and increased latency in DNS resolution across multiple regions.
During this time, users may experience issues with DNS resolution, or see errors returned when querying DNS records which are hosted on the DigitalOcean nameservers. Users may also experience DNS resolution issues while reaching out to their Managed Kubernetes Clusters.
We apologize for the inconvenience and will share an update once we have more information.
NYC2 Network Maintenance
2 May 2024 at 08:44
May 2, 13:44 UTC
Completed - From 12:14 UTC to 12:32 UTC, our Engineering team observed an issue where a subset of Droplets (any Droplets with an assigned public IP in the 192.241.160.0/19 range) and all Load Balancers in the NYC2 region were unreachable due to some backend changes made during the maintenance. Our Engineering team has resolved the issue and all services were reachable again at 12:32 UTC.
Due to such unforeseen issues, our Engineering team has decided to rollback this maintenance for now and will be rescheduling it at a later date.
We apologize for the inconvenience and the unexpected downtime to services. If you have any questions or continue to experience issues, please reach out via a Support ticket on your account.
May 2, 12:00 UTC
In progress - Scheduled maintenance is currently in progress. We will provide updates as necessary.
Apr 30, 15:32 UTC
Scheduled - Start: 2024-05-02 12:00 UTC
End: 2024-05-02 15:00 UTC
During the above window, our Networking team will be making changes to core networking infrastructure, to improve performance and scalability in the NYC2 region.
Expected Impact:
These upgrades are designed and tested to be seamless and we do not expect any impact on customer traffic due to this maintenance.
If an unexpected issue arises, affected Droplets and Droplet-based services could experience increased latency or disruption in public network traffic for a short period of time. If an unexpected issue does occur, our team is prepared to rollback to a safe state to quickly restore public networking. We expect that traffic would be impacted for a period of 5-10 minutes, at most, in that case.
If you have any questions related to this issue please send us a ticket from your cloud support page. https://cloudsupport.digitalocean.com/s/createticket
NYC2 Networking
30 April 2024 at 11:58
Apr 30, 16:58 UTC
Resolved - Our Engineering team has confirmed the root cause of this issue. Preparation work for the upcoming maintenance in NYC2 (https://status.digitalocean.com/incidents/z9r8gg95bqqm) was in-flight and had an unexpected impact, causing the connectivity outage. This was corrected and should not occur again.
All services were restored as of 16:06 UTC and we confirmed this incident impacted only a subset of customer Droplets in NYC2.
We apologize for the disruption and appreciate your patience while the root cause was confirmed. If you have any questions or concerns, please reach out to Support from within your account. Thank you.
Apr 30, 16:23 UTC
Monitoring - Our Engineering team has investigated and identified an issue with networking in our NYC2 region. From 15:54 - 16:06 UTC, services in our NYC2 region experienced a complete disruption in network availability. Users attempting to access Droplet and Droplet-dependent resources would have seen connections failing.
Our team has identified a breaking change and a rollback was completed. We are confirming full scope of impact and ensuring this issue will not reoccur.
We'll post another update soon.
Subsea Fiber Faults Between Europe and Asia
25 April 2024 at 19:36
Apr 26, 00:36 UTC
Resolved - Our Engineering team has continued to actively monitor the situation resulting from multiple subsea fiber faults in our Singapore (SGP1) region, and customers in Asia attempting to reach DigitalOcean resources hosted in our Amsterdam (AMS2, AMS3), London (LON1), and Frankfurt (FRA1) regions.
Our Support teams continue to surface customer escalations to our Networking team and work to shift to better/less latent routes will continue as well.
Repair of all cables from crews is still pending, and periodic network instability may continue to present itself during hours of high traffic, for multiple weeks until repairs are fully completed.
We will now close out this incident and provide any needed updates separately.
If users experience a disruption in service or have any questions, we invite them to submit a support ticket from within their account.
Thank you for your patience and understanding throughout this incident.
Apr 21, 11:56 UTC
Update - Our Engineering team continues to work with upstream providers to resolve network connectivity issues that are occurring in multiple regions. As a result of multiple subsea fiber faults between Europe and Asia regions, the issues appear to be a direct consequence of congestion resulting in packet loss and increased latency connecting to the SGP1 region. Customers in the Asian region are having difficulty reaching DigitalOcean resources located in Amsterdam (AMS2, AMS3), London (LON1), and Frankfurt (FRA1).
We have no ETA for the upstream issues being restored but we will communicate any relevant information as we have it. We apologize for the inconvenience.
Apr 20, 16:20 UTC
Identified - We've confirmed the degraded network performance in our first update is due to a cable cut, which occurred at approximately 18:00 UTC, April 19. This cable is located just west of Singapore and impacts the cabling system connecting 17 countries from Singapore to Europe. Users can read more about the cable here: https://www.submarinenetworks.com/en/systems/asia-europe-africa/smw5
We continue to monitor this situation and progress of the repair. Our Engineering team will also continue to tune for performance and alternate routes where possible, until the issue is resolved.
If you have any questions, please open a Support ticket from within your account.
Apr 20, 12:10 UTC
Investigating - Due to multiple simultaneous subsea fibre cuts between Europe and Asia, we are observing degraded performance for European customers attempting to reach DigitalOcean resources hosted in our Singapore (SGP1) region, and Asian customers attempting to reach DigitalOcean resources hosted in our Amsterdam (AMS2, AMS3), London (LON1), and Frankfurt (FRA1) regions.
Engineers are attempting to improve performance where possible, but as this issue is largely out of our control we do not expect a substantial improvement in performance until one of the fibre cuts is repaired.
We apologize for any inconvenience.
Keys for Object storage
16 April 2024 at 10:00
Apr 16, 15:00 UTC
Resolved - Our Engineering team identified and resolved an issue that affected creating new access keys for Spaces via control panel and API.
From 14:38 UTC to 14:56 UTC, users may have encountered errors while creating Spaces keys.
If you continue to experience problems, please open a ticket with our support team. Thank you for your patience and we apologize for any inconvenience.
NYC Network Maintenance
16 April 2024 at 08:00
Apr 16, 13:00 UTC
Completed - The scheduled maintenance has been completed.
Apr 16, 11:00 UTC
In progress - Scheduled maintenance is currently in progress. We will provide updates as necessary.
Apr 9, 21:13 UTC
Scheduled - Start: 2024-04-16 11:00 UTC
End: 2024-04-16 13:00 UTC
During the above window, our Networking team will be making changes to core networking infrastructure, to improve performance and scalability in the NYC region.
Expected Impact:
These upgrades are designed and tested to be seamless and we do not expect any impact to customer traffic due to this maintenance. If an unexpected issue arises, affected Droplets and Droplet-based services may experience increased latency or a disruption in network traffic for 2-3 minutes. We will endeavor to keep any such impact to a minimum.
If you have any questions related to this issue please send us a ticket from your cloud support page. https://cloudsupport.digitalocean.com/s/createticket
Multiple services down and API availability
16 April 2024 at 06:08
Apr 16, 11:08 UTC
Resolved - Our Engineering team has confirmed the full resolution of the issue impacting multiple services. The impact has been completely subsided and everything is back to normal for all the impacted services. Users should now be able to process events normally for Droplets, App Platform, and Cloud Control panel.
If you continue to experience problems, please open a ticket with our support team from your Cloud Control Panel.
Thank you for your patience and we apologize for any inconvenience.
Apr 16, 09:22 UTC
Monitoring - Our Engineering team confirmed that the fix applied has mitigated the issue impacting multiple services.
Users should no longer experience issues with the App platform, Droplet creation from the Cloud Control Panel, and API.
We are monitoring the situation and will post an update once we confirm the issue is fully resolved.
Apr 16, 09:04 UTC
Update - Our Engineering team is investigating reports impacting multiple services.
At this time, users may experience errors while accessing, deploying, and updating existing Apps from the Cloud Control Panel. However, the traffic to deployed apps is not impacted.
Users may also experience issues in accessing the Cloud Control Panel. Additionally, we have also received reports on droplet creation failures via the Cloud Control Panel and API. Cloud firewall services are also impacted.
We will provide an update as soon as we have additional information.
Apr 16, 08:12 UTC
Investigating - As of 06:40 UTC, our Engineering team is investigating reports of an issue with our App Platform service.
At this time users may experience errors while accessing, deploying, and updating existing Apps from the Cloud Control Panel. However, the traffic to deployed apps is not impacted.
We will provide an update as soon as we have additional information.
Droplet Create Failures in SGP1
8 April 2024 at 08:21
Apr 8, 13:21 UTC
Resolved - Our Engineering team has resolved the issues with Droplet create failures in our SGP1 region, and all systems should now be operating normally. If you continue to experience any problems, then please open a ticket with our support team right away. Thank you for your patience and we apologize for any inconvenience.
Apr 8, 12:48 UTC
Monitoring - Our Engineering team has implemented a fix to resolve the issue with Droplet creates and is monitoring the situation. We will post an update as soon as the issue is fully resolved.
Apr 8, 12:11 UTC
Investigating - Our Engineering team is investigating an issue with Droplet creation failures in our SGP1 region. During this time, you may experience issues while creating Droplets in the region.
We apologize for the inconvenience and will share an update once we have more information.
App Platform in SGP1
2 April 2024 at 11:15
Apr 2, 16:15 UTC
Resolved - As of 16:00 UTC, our Engineering team has confirmed full resolution of App platform service in SGP1 region.
If you continue to experience problems, please open a ticket with our support team from your Cloud Control Panel. Thank you for your patience and we apologize for any inconvenience.
Apr 2, 15:42 UTC
Monitoring - As of 15:35 UTC, our Engineering team has successfully redeployed all the impacted apps in the SGP1 region. We are actively monitoring the situation and will provide an update once the incident has been fully resolved. Thank you for your patience and we apologize for the inconvenience.
Apr 2, 14:55 UTC
Investigating - As of 14:27 UTC, our Engineering team has investigated and identified the root cause of an issue with our App Platform service in the SGP1 region. At this time, a subset of Apps in SGP1 are offline. Users can redeploy their App(s), which will bring them back online.
For users who do not immediately redeploy, our Engineering team is working to do so, to bring the impacted Apps back online.
We will provide an update as soon as we have additional information.
Managed Databases Control Plane
27 March 2024 at 00:01
Mar 27, 05:01 UTC
Resolved - Our Engineering team has confirmed that this incident has been fully resolved.
We appreciate your patience throughout this process and if you continue to experience problems, please open a ticket with our support team for further review.
Mar 27, 04:42 UTC
Monitoring - Our Engineering team has implemented a fix to resolve the issue with our Managed Databases services. At this time, users should no longer face issues creating, resizing, or updating trusted sources for PostgreSQL, MySQL, Redis, and Kafka clusters, in any region.
We are monitoring the situation closely and will post an update as soon as we confirm the issue is fully resolved.
Mar 27, 03:55 UTC
Identified - As of 00:30 UTC, our Engineering team has identified an issue that impacts the control plane for Managed Databases. Users may experience errors with creating, resizing, or updating trusted sources for PostgreSQL, MySQL, Redis, and Kafka clusters, in all regions.
Due to updates to trusted sources being impacted, connections to Database clusters from newly added trusted sources will fail. This includes new Managed Kubernetes nodes, Droplets, and Apps using Databases.
Our team is working to deploy a fix and we will provide another update soon.
Core Infrastructure Maintenance
26 March 2024 at 12:28
Mar 26, 17:28 UTC
Completed - Scheduled maintenance has completed ahead of schedule, with no observed customer impact. Thank you for your patience. If you have any questions or concerns, please reach out to the Support team from within your account.
Mar 26, 17:00 UTC
In progress - Scheduled maintenance is currently in progress. We will provide updates as necessary.
Mar 21, 18:15 UTC
Scheduled - Start Time: March 26 17:00 UTC
End Time: March 26 18:00 UTC
During this time, our Engineering Team will be performing maintenance to failover an internal service from one cluster to another.
This maintenance has been previously conducted with limited impact and our team has done extensive planning and testing to ensure a smooth failover, with the least disruption possible.
Existing infrastructure (including Droplet and Droplet-based services networking) will continue running without issue.
If the failover period lasts longer than expected, there may be customer impacts with associated services including:
Droplet creates with a root password
Droplet root password resets
MongoDB cluster creates
Let’sEncrypt certificate creation (for Load Balancers and Spaces)
LoadBalancer creation with certificates
Spaces key creation
Marketplace (Add-Ons) will be unavailable for both vendors and users
App Platform builds and deploys may see latency
Users will be unable to fetch CSV invoices
Bulk actions in the Spaces UI
At this time, we do not expect to see any of the above listed impacts during maintenance, but are prepared for the worst case if needed.
If you have any questions or concerns, please reach out to the Support team from within your account.
